Post-training
Rethinking the Model Development Lifecycle: Does Thinking Mid‑Training Help Post-Training?
Model weights · Interleaved-thinking dataset
Shaping Model Behavior
Modern model training is a lifecycle. A base model is pretrained, adapted through mid-training, extended for context length, taught thinking formats, preference-tuned, and then optimized with verifiable rewards.
Agentic post-training asks that model to reason through uncertainty, plan over longer horizons, use tools, revise its beliefs, and recover from mistakes. These behaviors are usually optimized late in the lifecycle, and recent RLVR work argues that late optimization often improves sampling efficiency more than it creates fundamentally new reasoning patterns.
Can more of that behavior be shaped earlier in the lifecycle, particularly during pretraining and mid-training, so the model arrives at agentic post-training already prepared for it?
Rephrasing a pretraining corpus with synthetic data is not new. Synthetic bootstrapped pretraining goes further: it learns relations between documents in the corpus, then uses those relations to synthesize new pretraining data. The learning problem around the corpus can change too. Instead of passive exposure to text, the training loop can ask whether the model can generate a better continuation, insert local reasoning into the text, and use those thoughts to predict what follows.
Synthetic pretraining and active data design are the closest neighboring lines. Hugging Face’s Synthetic Data Playbook is a practical guide to prompt design, data mixing, small generators, and train-and-evaluate loops. Tufa Labs reports a benchmark-positive version of very-small-model synthetic pretraining. The Berkeley Sky Computing Lab and NVIDIA lecture treats it as active curriculum design. Vintage Data argues that synthetic pretraining is data design moving earlier in model development. Large-scale studies of synthetic data in LLM pre-training show that the benefits are conditional: rephrased synthetic data can help in mixtures, while pure generated textbook-style data can hurt downstream generalization.
Most proposals for moving reasoning earlier share a design choice that is rarely tested on its own: where the future text goes. Thinking mid-training’s SFT stage and reasoning continued pretraining put a teacher’s thoughts into the training target, and the teacher usually writes them after reading the text they precede. Reinforcement Pre-Training, RLP, and RLMT keep the future text in the reward instead: the model writes its own reasoning and is scored on how well it predicts what comes next. ExpRL makes the same split for reference solutions in math mid-training. This post measures what that choice does to a small model, stage by stage, using the same pretraining chunks it would normally only imitate.
I ran the full pipeline at small scale, measured what each stage teaches and what survives into RL, then ran a controlled, pre-registered follow-up on the mechanism the first experiment pointed to. Together they support three findings:
- The pretraining and SFT stages install real, measurable signals at 0.6B. Self-improving pretraining won 81 of 128 judged continuation comparisons against the base, and thinking SFT installed a thought interface the model reads: swapping in the thought from a different passage costs about 4 bits on the real continuation.
- A teacher thought’s value comes from what the teacher could see, and that is what the student learns to copy. A thought from a teacher that saw the continuation saves 7.5 bits on the next 128 tokens; the same teacher without it saves 1.1 (Figure 1). A student trained on such hindsight thoughts asserts 0.37 unsupported names and numbers per thought, against 0.25 when trained on thoughts written without hindsight, and removing the future facts from the hindsight thoughts brings it to 0.24 (Figure 2).
- RL decides what carries forward. After 200 steps of GSM8K RL, none of the mid-trained models that ran RL writes thoughts, their differences disappear, and the untouched base given the same RL finishes 3 to 4 points ahead of all of them (Figure 3). A mid-training signal has to clear that bar.
For anyone building a thinking corpus, the results give a diagnostic and three design rules. The teacher’s foresight comes from the annotation instruction, and it can be measured on a sample of annotations before any training. The next experiment follows from that: put the teacher’s privileged view in the reward that scores the student’s own attempts, instead of in text the student copies.
From Pretraining Text to Training Environment
Tan et al. propose two linked training ideas. The first is self-improving pretraining.Self-improving pretraining uses stronger post-trained models to improve earlier stages of the training pipeline. The second is thinking mid-training.Thinking mid-training is Tan et al.’s term for the mid-training arc that adds interleaved reasoning to pretraining text. SFT teaches the thought format, and RL mid-training (RLMT) then rewards thoughts that help predict the rest of the chunk.
Self-improving pretraining changes what the model learns from a pretraining chunk. In standard next-token pretraining, the model sees a prefix and learns to imitate the suffix that happened to come next in the corpus. Tan et al. instead use a stronger post-trained model in two roles: it rewrites the suffix into a higher-quality target, and it judges the original suffix, the rewrite, and K rollouts from the current policy. The update favors the continuation judged best, so the signal of interest is whether the model’s own rollouts start beating the data suffix, not lower loss on the original text.
Thinking mid-training works one stage later. Mid-training is the stage between base pretraining and final post-training, where labs often adapt a model toward longer context, reasoning formats, domain mixtures, or other broad capabilities before task-specific alignment. Tan et al. use this stage to teach a model to interleave short thoughts inside ordinary text. A teacher model inserts local reasoning spans into pretraining chunks, the student learns that format through supervised fine-tuning, and then RL mid-training (RLMT) rewards the student when its generated thought helps predict the held-out continuation. A related line of reasoning continued pretraining synthesizes hidden thoughts from ordinary text, treating the observed document as the product of an implicit reasoning process.
The same corpus becomes several training environments in turn: continuation preference data for self-improving pretraining, interleaved-thinking data for SFT on the thought interface, and prefixes for RLMT.
The model generates K alternative continuations. A judge ranks them against the original suffix, and Online DPO favors the highest-scoring candidate.
A teacher model inserts short thoughts at semantically appropriate positions. The student learns the format through SFT, where the original text still concatenates back to the unaltered chunk.
The model generates a thought, then a predicted suffix. The judge scores the predicted suffix against the true continuation, and reward depends on whether the suffix is good enough.
Training terms
- Self-Improving Pretraining uses a stronger post-trained model to supervise pretraining of the current policy. The data stream is split into a prefix and a suffix (the last N tokens). The post-trained model can rewrite the suffix into a higher-quality target or judge the original suffix, the rewrite, and K rollouts from the current policy. Reinforcement learning pretrains the policy using the judge’s reward signal.
- Online DPO (direct preference optimization) is the RL objective Tan et al. use during self-improving pretraining. For each prefix, the judge scores a candidate set (original suffix, rewrite, K rollouts), and the update takes the highest-scoring candidate as chosen and the lowest as rejected. Unlike GRPO, DPO is off-policy, so it can learn from candidates the current policy did not produce.
- Interleaved thoughts are short reasoning spans inserted by a teacher model into ordinary pretraining chunks at semantically appropriate positions. The augmented chunk alternates segments of original text with inserted thoughts, and the original segments still concatenate back to the unaltered chunk. The student first learns the format through SFT and is later rewarded for thoughts that help predict the rest of the chunk.
- RLMT (reinforcement learning mid-training) is the second mid-training phase. Each augmented pretraining chunk is split into a prefix and a ground-truth suffix. From the prefix, the model generates a thought followed by a predicted suffix. An LLM judge compares the predicted suffix to the ground-truth suffix and emits a binary reward, which the RL update maximizes. The reward is on the thought-conditioned suffix prediction, not on the thought itself.
- Hindsight and causal thoughts. A hindsight thought is written by a teacher that has read the whole passage, as in the paper’s annotation prompt. A causal thought is written at the same position by a teacher that has seen only the text before it.
- Preview share is the share of a thought’s content words that are new at that point in the passage and appear later in it.
- Unsupported specifics are numbers and mid-sentence capitalized words in a model’s own thought that appear nowhere in the passage.
- Latching is Swamy et al.’s term for an imitation learner that repeats its own recent actions. Here an answer counts as latched if some 16-token span occurs three or more times.
- Dr. GRPO is a GRPO variant without per-response length and standard-deviation normalization.
A Small-Scale Lifecycle Experiment
I ran the adaptation on Qwen3-0.6B-Base, using FineWeb-Edu materialized into ordinary pretraining chunks of prefix and true suffix. That structure stayed constant; only the learning problem wrapped around it changed.
The first stage was self-improving continued pretraining with Online DPO. For each prefix, the model generated 16 candidate continuations. A larger Qwen judge compared the original suffix and the policy rollouts, using full-pairwise comparisons rather than a single pivot comparison. I left the teacher rewrite out of this pool on purpose, following the ‘suffix vs 16 rollouts’ Online DPO variant in Tan et al.’s Table 6. The update pushed the model toward the judged-better continuation and away from the judged-worse one.
The second stage turned the same kind of pretraining chunks into interleaved-thinking examples. A teacher model (Qwen3.6-35B-A3B) inserted short local thoughts into the text while preserving the original content, reusing the rewrite role from Tan et al.’s self-improving pretraining, moved into mid-training. Like the rewriter, it read the whole chunk before writing. The student was then supervised on the augmented sequence, both the original text and the inserted thoughts. This stage was meant to install the interface (where thoughts appear, what they look like, and how they connect to nearby text), not to prove reasoning improvement by itself.
The third stage was RL mid-training. The model received a prefix, generated a thought, then predicted the suffix, and a judge scored that prediction against the real suffix. The reward did not grade the thought directly, only whether the thought-conditioned continuation was good enough.
To compare, one lineage started from the original Qwen3-0.6B-Base and the other from the self-improved checkpoint. Both were trained on the same interleaved-thinking data, then went through the same RLMT setup. Did self-improving pretraining leave the model better prepared for later thinking mid-training?

The comparison isolates whether self-improving continued pretraining leaves the model better prepared for later thinking mid-training. Both lineages use the same interleaved-thinking data and RLMT objective.
| Stage | Input | Learning problem | Output |
|---|---|---|---|
| Self-improving continued pretraining | FineWeb-Edu prefix and suffix chunks | Choose between the original suffix and K=16 policy rollouts using full-pairwise judge comparisons and Online DPO | A self-improved base checkpoint |
| Interleaved-thinking SFT | The same kind of raw chunks, augmented by a teacher | Learn to reproduce original text with short local thoughts inserted | A model that can use the thought interface |
| RL mid-training | Prefixes from the augmented corpus | Generate a thought, predict the suffix, and receive reward from suffix quality | A model optimized through a sparse thought-conditioned reward |
| Evaluation | Held-out chunks, then a controlled follow-up with GSM8K RL | Separate continuation quality, what a thought is worth to the reader, what the student learns to write, and what survives RL | Evidence about where each stage’s learning signal comes from |
Results
Continued pretraining improved judged continuation quality
On held-out prefix-suffix chunks, the self-improved checkpoint beat Qwen3-0.6B-Base on 81 of 128 pairwise continuation judgments, a 63.28% win rate.
Training dynamics moved in the same direction. The rate at which the judge selected a policy rollout rather than the original suffix rose from 62.5% to 74.6%, and the DPO marginDPO margin is the average log-probability gap between chosen and rejected continuations across training pairs. A larger margin means the policy more strongly prefers the judged-better continuation. rose to 0.19.
Raw suffix NLL moved the other way, from 2.56 to 2.60. Online DPO optimized judged continuation quality, not exact imitation of the original suffix.
SFT installed the thought interface
The final interleaved-thinking dataset had 8,704 rows (8,192 train, 512 validation). It averaged 4.39 thoughts per row, had zero malformed rows, and preserved the raw text closely, with average raw word coverage of 99.98%.
SFT on this dataset taught the model to predict thought tokens. Thought NLLThought NLL is the negative log-likelihood the model assigns to the inserted-thought tokens specifically, measured separately from the surrounding original text. Lower means the model fits thoughts in the trained format better. dropped from 4.24 for the raw baseline to 3.16 for the base model and 3.14 for the self-improved model, each after training on interleaved thoughts.
SFT installed the interface but did not by itself show whether thoughts were useful. The pre-RLMT comparison between the self-improved and base thinking models tied exactly at 64-64, which made the thought channel itself the next thing to measure.
Thought text steers what the model predicts
To measure what a thought is worth without a judge, I used bits saved:Bits saved is how much more probable a thought makes the true next 128 tokens, in bits, relative to no thought. Positive means the thought helped the model predict real text. at a teacher-thought position in each of 494 held-out chunks, insert a thought and measure how much more probable it makes the real text that follows. The comparisons were registered before I ran them. This tests whether interleaved thoughts are just formatting or actually steer what the model expects next.
They steer it. Swapping in the teacher thought from a different passage costs 3.8 to 3.9 bits relative to the matched one, in every checkpoint, and swapping the model’s own thoughts across passages costs 2.7 to 3.6 bits. Matched teacher thoughts beat generic filler by 3.3 to 3.5 bits. The thought channel had become a real handle on the model’s predictions.
The model’s own thoughts were the open problem. Across the 494 chunks they cost 12 to 12.5 bits against no thought (10.5 on Figure 1’s 128 passages), mostly from the format: an empty thought alone costs about 10 bits, and its thoughts rarely close (0.2-0.4% end with </think> within 48 tokens). Useful thoughts already exist in its sampling distribution, though: about one in six of its sampled thoughts (16-19%) saves bits. The answer to the lineage question is that the thought channel looks the same in all four checkpoints. Self-improving pretraining and RLMT each moved the model’s own thoughts by less than half a bit, so the channel’s behavior was set by the SFT data, which points the analysis at the teacher that wrote it.
The positive result is causal sensitivity.Causal sensitivity means that changing the thought text changes the model’s predictions under the same prefix. Here, swapping in another passage’s thought cost 3 to 4 bits, so the thought text was not just formatting. The open problem is self-generation, and the style of the model’s thoughts is the clue to its cause. Read directly, they look like confident continuations of the passage. After a D-Day weather report, one described “a wind of 35 knots” and a boat that “would be sunk,” neither of which the text mentions.
Teacher thoughts carry their value by reading ahead
The teacher wrote its thoughts after reading the whole chunk, and the paper’s annotation prompt asks it to “copy details which are specific to the text and would otherwise be almost impossible for anyone to predict.” A thought written that way previews the text that follows it. The student, at the same point in the passage, has not seen that text. Imitation learning calls this mismatch the imitation gap (Weihs et al.): a learner copying an expert who sees more than it does learns to act as if it had the expert’s information.
Figure 1 measures how much of a teacher thought’s value comes from that view. I had a local teacher, Qwen3.5-4B, write a thought at the same point in 128 passages twice, with the same prompt and about the same length (22 and 24 words), once seeing only the text so far and once also seeing the continuation. With the continuation its thought saves 7.5 bits [5.3, 9.8]; without it, 1.1 [−0.6, 2.8].
Part of the hindsight value is literal copying, so I also masked every suffix token whose word appears in the thought but not in the prefix. The gap narrows to 2.9 bits [1.8, 3.9] and holds, because hindsight leaks paraphrase as well as words (“the next paragraph’s shift to mangrove deterioration”). Even Qwen3-0.6B-Base, which never trained on thoughts, prefers the hindsight thought by 6.7 bits [4.9, 8.4]. On these 128 passages the released teacher sits between the two, at 2.9 bits. Across all 494 chunks, most of its value is the words it previews: it saves 1.4 bits, and 0.5 [−0.3, 1.4] once those words are masked.
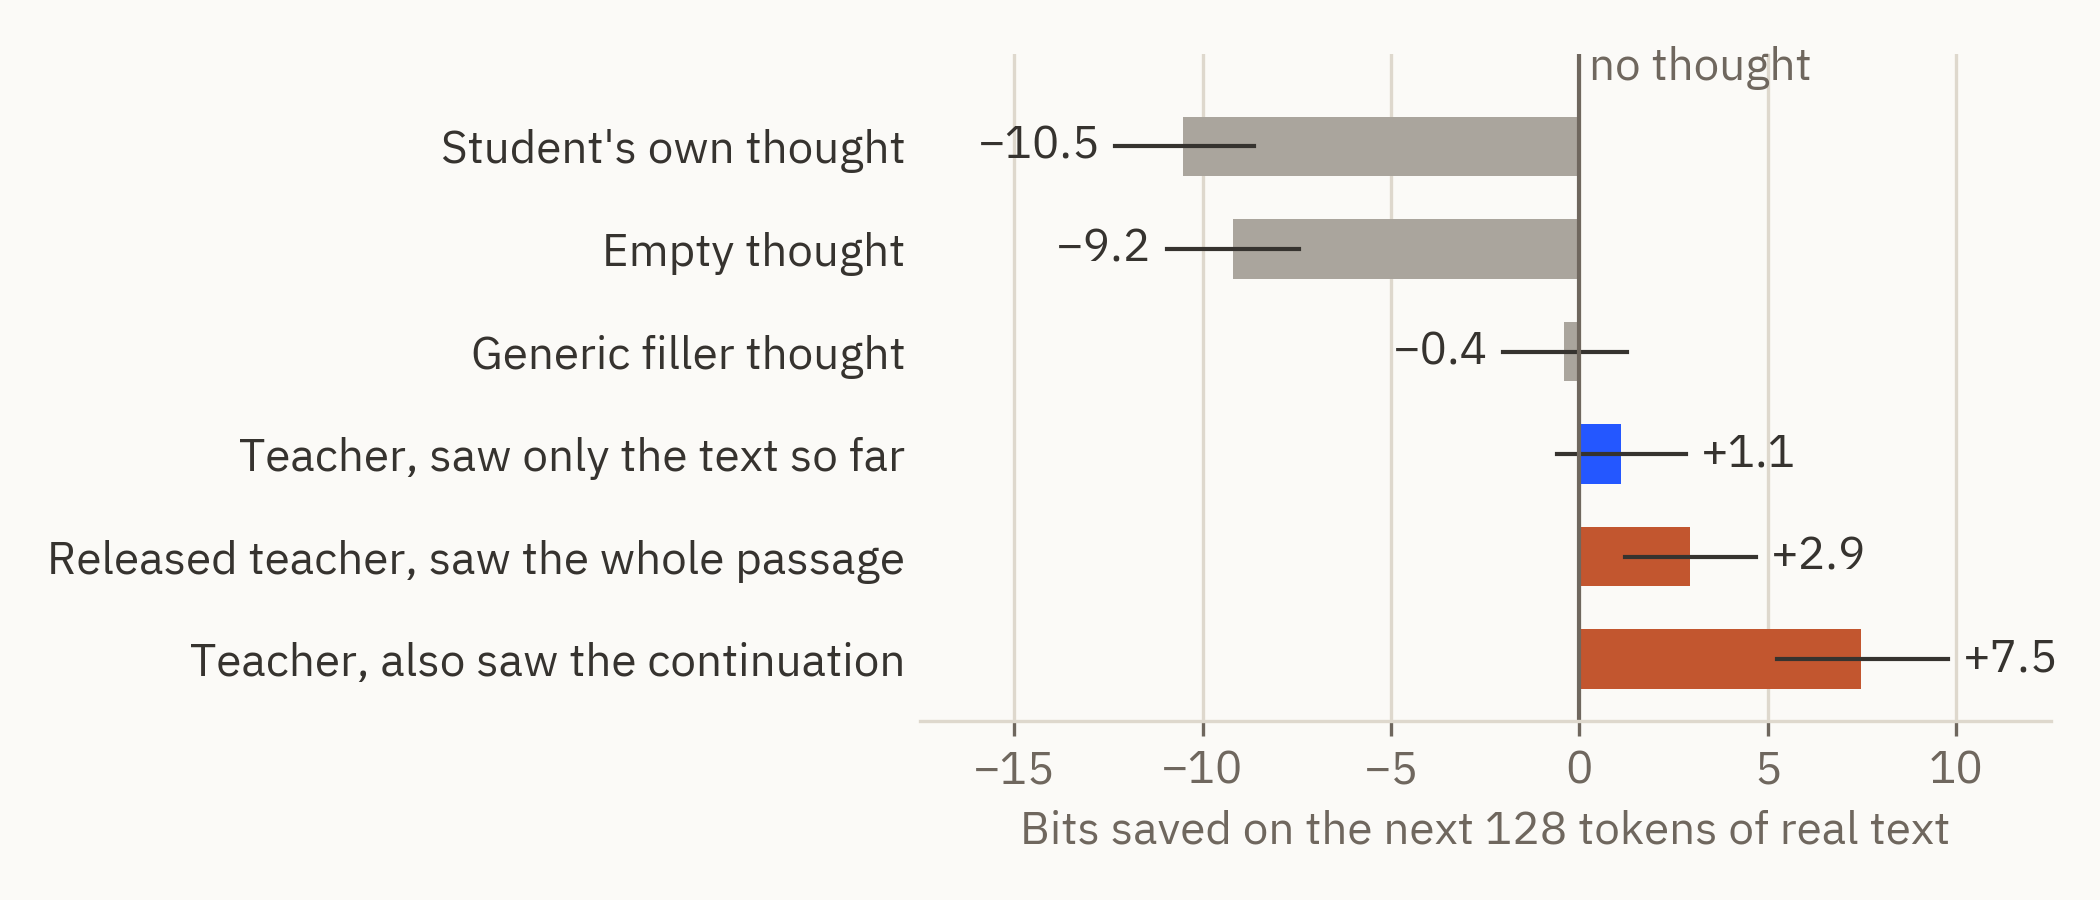
Figure 1. A thought helps the model predict real text mainly when its writer had seen that text. Bits saved on the true next 128 tokens, relative to no thought, read by the full 0.6B pipeline (self-improved, thinking SFT, RLMT) on the 128 held-out passages where every condition was scored. The other three checkpoints are within 0.3 bits on every bar. Grey: the student’s own thought (mean of 8 samples) and two content-free controls. Blue and orange: the same local teacher (Qwen3.5-4B) without and with the continuation, and the released teacher that wrote the training data. Lines are 95% bootstrap intervals over passages.
This explains why the model learned to use thoughts before it learned to write them. Most of what made the teacher’s thoughts useful was information the student never has at that point in the text. Testing that directly needs students trained on hindsight and non-hindsight thoughts that are otherwise matched.
A Controlled Test of the Teacher’s View
I pre-registered that test on LiquidAI’s LFM2.5-1.2B-Base, chosen among four base models under 2B parameters by a rule I fixed before measuring them. gpt-oss-20b annotated 20,947 FineMath and DCLM passages, about 5.5 thoughts per passage, and I mid-trained one copy of the base on 20M tokens of each of four corpora:
- Plain text: the same passages without thoughts.
- Hindsight thoughts: the teacher sees the whole passage and follows the paper’s annotation prompt.
- Causal thoughts: a thought at each of the same positions, written by the same teacher seeing only the text before it and told not to invent specifics.
- Hindsight, future facts removed: each hindsight thought rewritten to drop anything the text has not yet stated, keeping every calculation. I added this arm after seeing the pre-RL results and the first RL seed, and registered its checks and predictions before any of its outcomes.
The manipulation does what it should. Take the share of a thought’s content words that are new at that point and appear later in the passage. The opening hindsight thought, written before any text, previews 24% of its words from the text ahead, against 2.6% for the causal one; later thoughts preview 8.4% and 3.8%. Lengths are matched (median 47 and 49 words).
The annotation instruction drives that foresight. With the passage in view, it draws about 11 names and numbers into each opening thought, most of them copied from text the student has not reached. In a smoke run where the teacher saw nothing, the same instruction still produced about 8 per opening thought, 97% of them invented: a number-theory page became “a data engineer named Alex” setting up “a Spark cluster on AWS EMR.”
The plain-text, hindsight, and causal models then ran the same GSM8K RL, Dr. GRPO for 200 steps with three seeds each. Every measure is judge-free: an answer checker for math, and string matching against the true passage for thoughts. I fixed the arms, metrics, and decision rules in a pre-registration before any run, recorded every later change in a dated addendum written before the outcome it affected, and label checks added after an outcome as post hoc.
Imitation passes the teacher’s foresight on as confident guessing
To see what each model learned to write, I had it generate its own thoughts at up to three fixed points in 1,967 held-out passages, four samples each, and counted names and numbers that appear nowhere in the passage. The hindsight-trained model produced 0.37 per thought and the causal one 0.25, a difference of 0.13 [0.11, 0.15] that meets the pre-registered criterion.
Post hoc checks support reading the count as confabulation. About 60% of the excess comes from thoughts that never close: 7% of hindsight thoughts run to the length cap, against 3% of causal ones. On thoughts that close normally, the excess is 0.05 [0.03, 0.07]. “Unsupported” means absent from the passage, not false, so the count includes true background knowledge such as “Pythagorean.” In a hand audit of 12 random closed thoughts per model that contained an unsupported number, about 5 of the hindsight numbers were invented or false, against about 2.5 of the causal ones; most of the rest were true background or derivable arithmetic. The audit is too small for a rate, but it shows the excess is not mainly recall. Two hindsight errors on web text, chosen to illustrate: “The Aggie ROTC program is a part of the University of Texas at Austin” (the Aggies are Texas A&M), and a list of Gandhi’s key events that includes the “Nobel Peace Prize.”
The fourth model locates the source precisely. Trained on hindsight thoughts with future facts removed, its own thoughts carry 0.24 unsupported specifics: 0.13 [0.10, 0.16] fewer than hindsight and no different from causal (−0.004 [−0.03, 0.02]). That was the pre-registered prediction. The drop is concentrated on web text, from 0.42 to 0.18, where the text ahead holds facts. On math text, where it mostly holds derivations, removing future facts changes little (0.32 and 0.30).
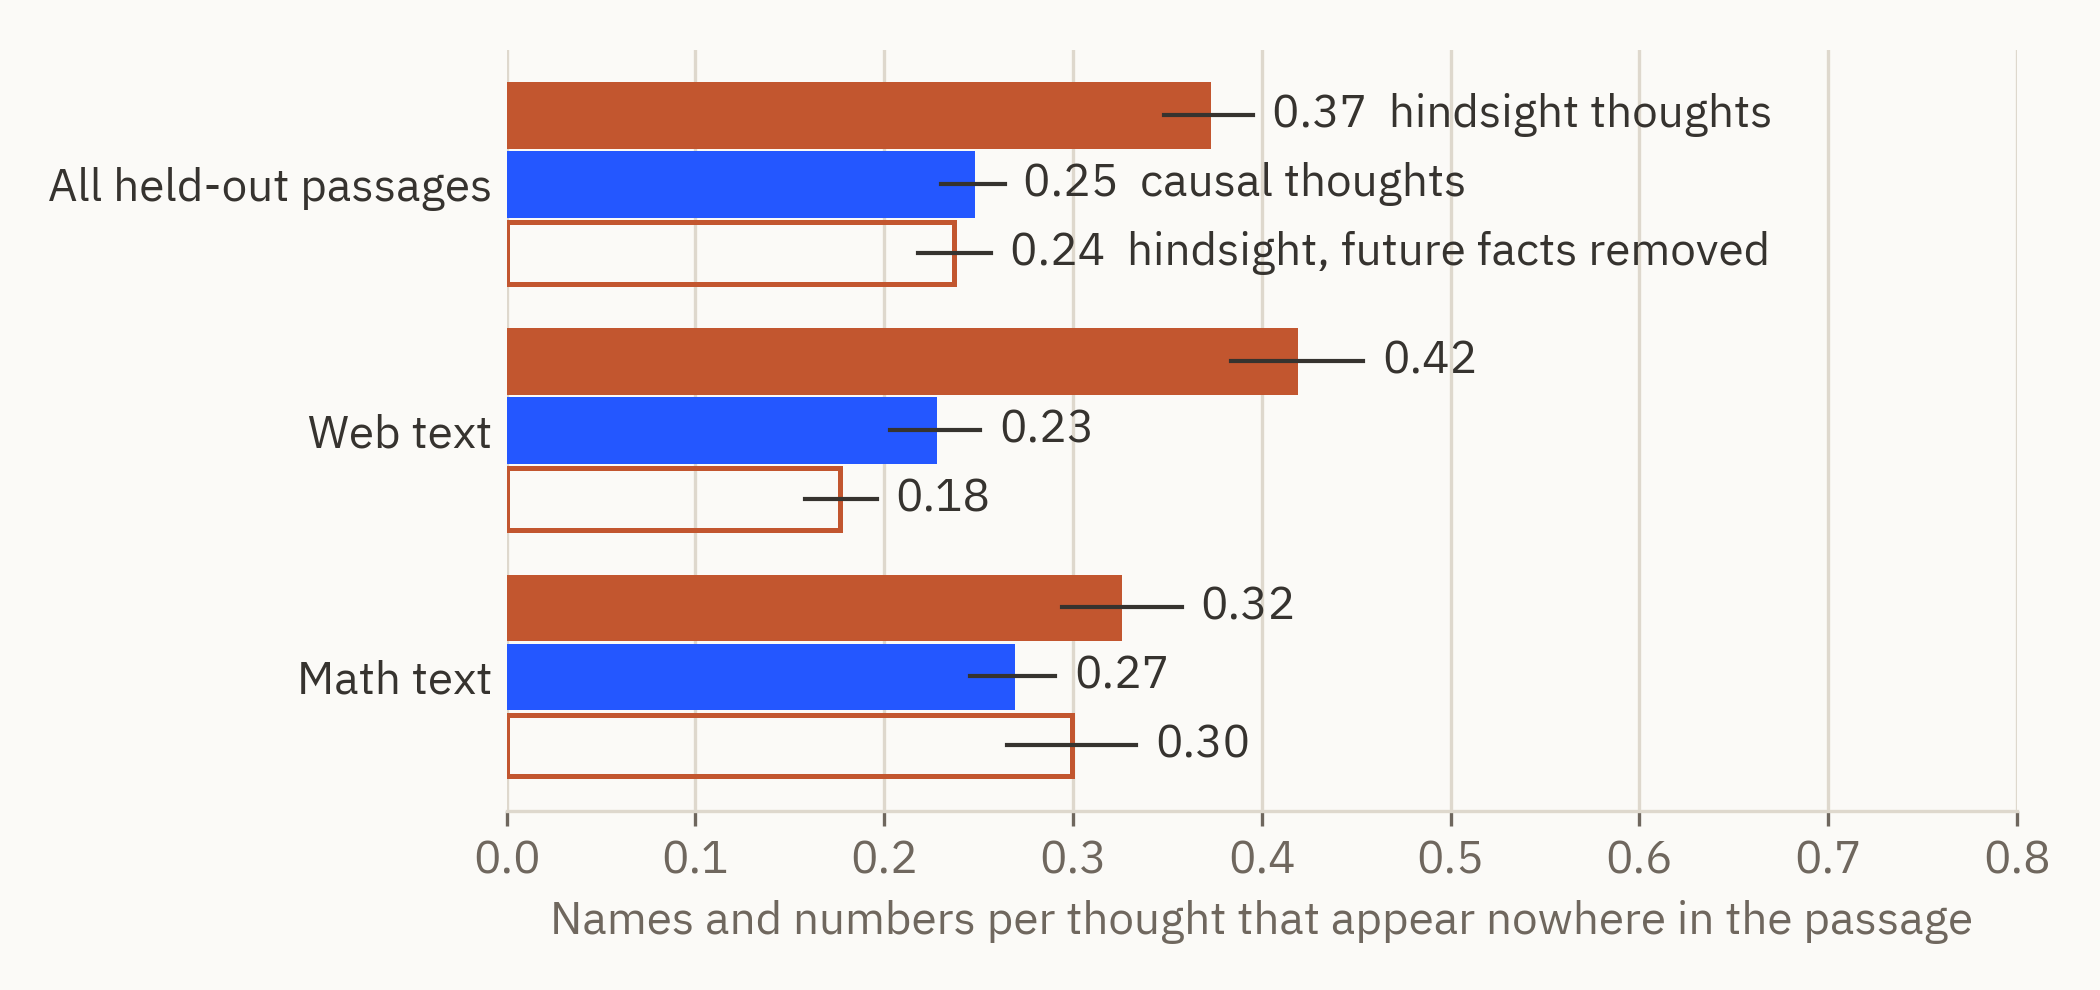
Figure 2. Removing the facts a teacher could only know by reading ahead removes the guessing its thoughts teach. Names and numbers per thought that appear nowhere in the passage, sampled from each mid-trained model at up to three positions in each of 1,967 held-out passages. Solid orange: trained on hindsight thoughts. Blue: causal thoughts. Outlined orange: hindsight thoughts with future facts removed and calculations kept. Lines are 95% intervals from resampling passages. The overall comparison was pre-registered; the web and math split was registered as exploratory before any of these outcomes.
The same edit also removed the hindsight model’s coverage edge before RL. Sampling 16 answers per problem on 200 GSM8K test problems, the hindsight model solved 55% at least once, against 48% for causal and 46% for plain text, though the hindsight-versus-causal interval includes zero (+7 [−1, 15]). With future facts removed, the model solved 44%, clearly below hindsight (−11 [−18.5, −3.5]). Both what hindsight imitation adds and what it costs appear to come from the part of each thought that previews the text, and that is the part a corpus builder can measure and control.
RL decides what carries forward
Before RL, most of both thought-trained models’ GSM8K answers opened a <think> span: 84% for hindsight and 70% for causal. More than half of their answers latched, 59% and 57% against 8% for plain text, and only 34% and 42% finished within the token budget, against 89%. That is the pattern imitation-learning theory predicts for offline copying (Swamy et al.), and it came from imitating teacher thoughts of either kind.
RL removed all of it. By step 200 none of the models wrote thoughts, latching in the mid-trained models fell below 2%, nearly every answer finished, and the three mid-trained models converged (Figure 3): 70.9% for plain text, 70.7% for hindsight, and 70.1% for causal. Hindsight minus causal was +0.6 points [−1.5, 2.8]. My pre-registered rule calls that inconclusive, because it required hindsight to come out no better than causal, but the interval rules out a hindsight advantage of 3 points or more.
The untouched base, given the same RL as a reference, reached 73.8% [71.6, 75.9]. Every mid-trained model finished 2.9 to 3.7 points below it, with intervals that exclude zero. That is the bar a mid-training corpus has to clear, and at 20M tokens none did.
My reading is that a strong modern base already carries the answer format RL needs, and 20M tokens of mid-training loosened it: before RL, every mid-trained model’s GSM8K answers ran two and a half to three times longer than the base’s. Before RL the gap was much larger. The untouched base solved 75.5% of 200 GSM8K test problems within 16 samples, against 44-55% for the mid-trained models. In a check added after the first RL results, it solved 60% of 262 MATH level 4-5 problems within 32 samples, against 38-45%. GSM8K RL recovered most of that: afterward, with one seed each, the hindsight model and the base both solved 76% of those MATH problems within 32 samples, and the causal model 71%.
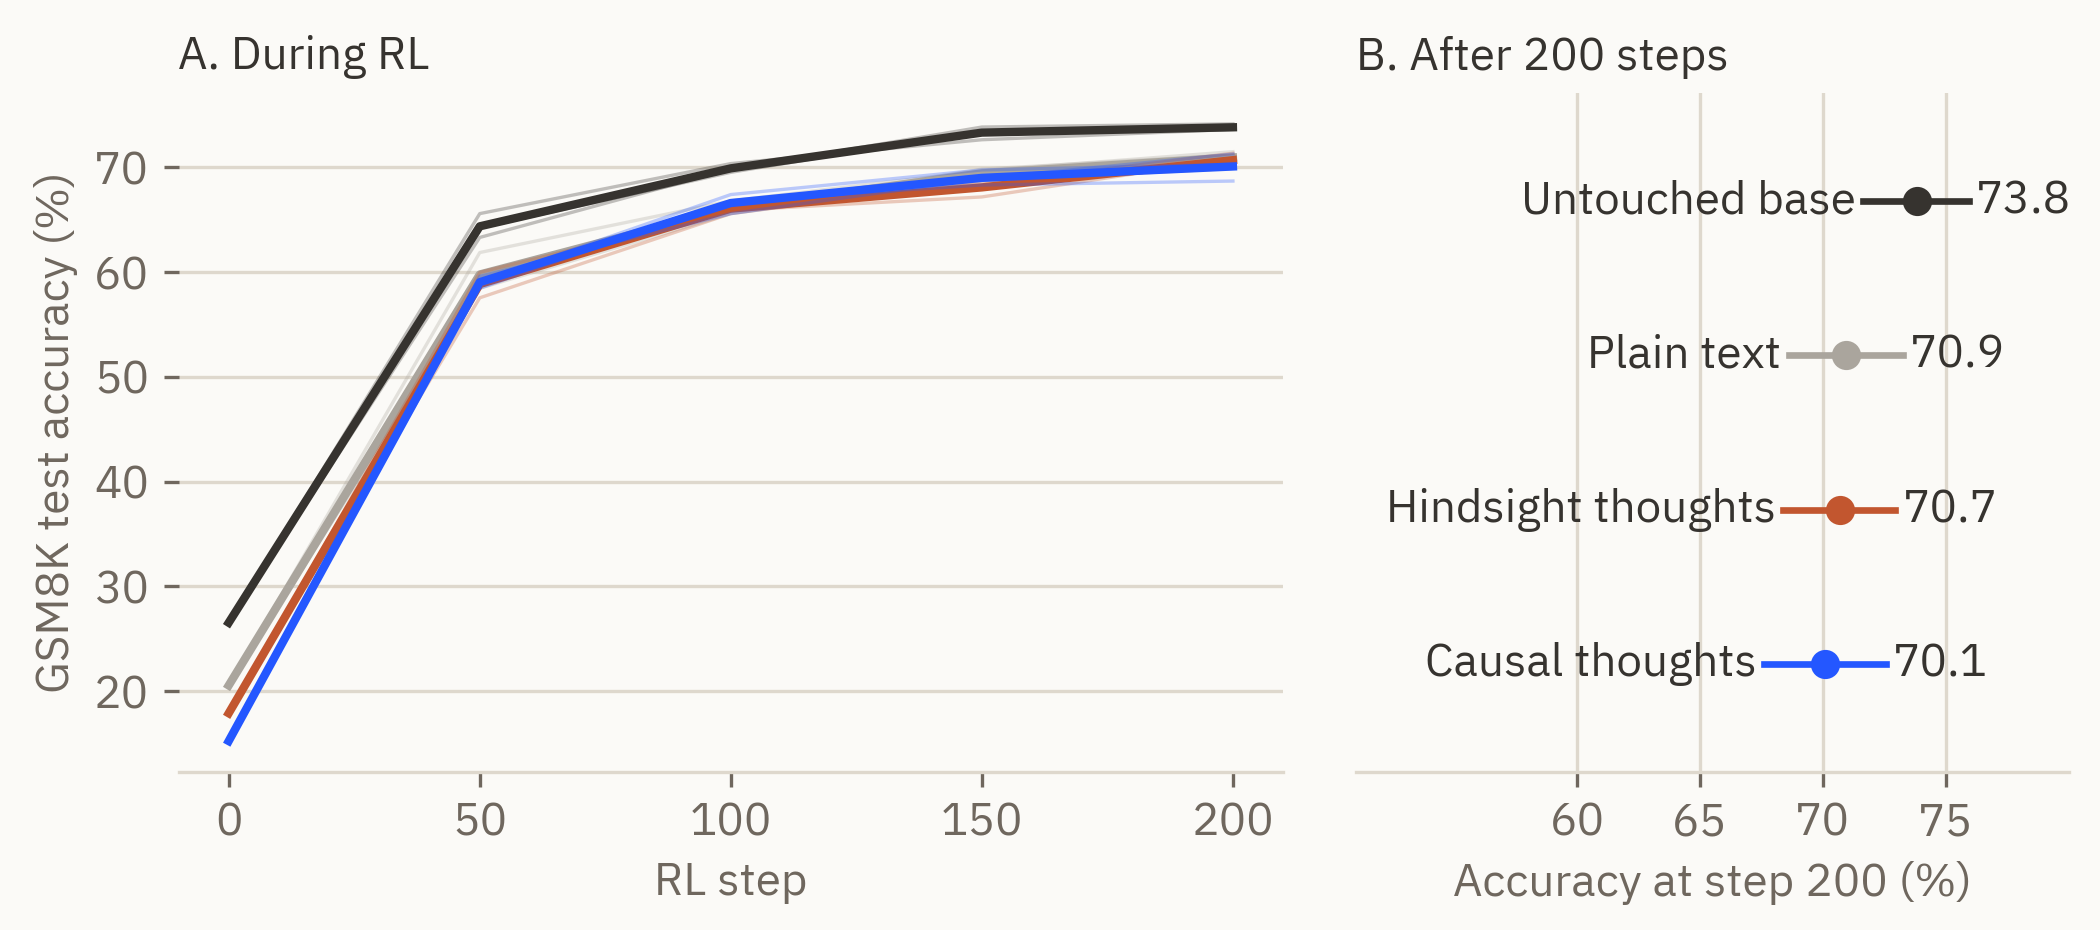
Figure 3. GSM8K RL erases the differences between mid-training corpora, and the untouched base finishes ahead of all of them. A: greedy accuracy on the 1,319-problem GSM8K test set every 50 RL steps; thick lines are means over three seeds, thin lines single seeds. B: accuracy at step 200 with 95% intervals from a bootstrap over seeds and problems. Orange and blue match Figures 1 and 2; grey is plain text and black is the base with no mid-training. The future-facts-removed model did not run RL: a rule registered before the final RL results dropped it once the other three converged.
RL also reshaped the thoughts themselves. Forced to think on the same held-out passages after RL (one seed each, exploratory), both models assert more unsupported specifics than before, 0.64 for hindsight and 0.60 for causal, in longer, confident recitals: “the 2020 census was released on April 1, 2021.” Hindsight’s excess shrinks to 0.04 and reverses on thoughts that close. After RL, how a model writes thoughts depends more on the RL than on the mid-training content.
| Stage | Primary evidence | Interpretation |
|---|---|---|
| Self-improving continued pretraining | 81/128 held-out pairwise continuation wins over Qwen3-0.6B-Base | The self-improved checkpoint produced better judged continuations |
| Interleaved-thinking SFT | Thought NLL fell from 4.24 to 3.14-3.16; swapping in another passage’s thought costs 3 to 4 bits | SFT installed a thought interface the model reads |
| RL mid-training | The model’s own thoughts moved by less than half a bit | The thought channel was set by the SFT data |
| Teacher’s view | Hindsight teacher thoughts save 7.5 bits, causal ones 1.1 | A teacher thought’s value comes from reading ahead |
| Controlled follow-up | 0.37 unsupported specifics per thought after hindsight imitation, 0.25 causal, 0.24 with future facts removed | Imitation passes the teacher’s foresight on as confident guessing |
| GSM8K RL | Mid-trained models converge at 70.1-70.9%; the untouched base reaches 73.8% | RL decides what carries forward |
Implications for Training
Small language models are usually framed as vertical tools that work when the task is narrow, the domain is bounded, and the behavior is easy to specify. A small model can also be specialized for the behaviors later training will need to refine. The question is whether early training can make it easier to turn into a reliable agent later, not only whether it can solve a vertical task.
Tan et al. argue that reasoning should be trained earlier in the lifecycle because raw pretraining text does not expose the intermediate reasoning behavior later post-training has to optimize. I read this experiment as a small-scale version of that idea: the model learned a continuation preference, a thought interface, and a rewardable suffix-prediction loop, and the thought channel became behaviorally causal. The follow-up adds where the reasoning signal in a thinking corpus comes from, and that gives the pipeline three concrete design rules.
- Measure the teacher’s view before training. Preview share is cheap to compute on a sample of annotations, and a causal annotation prompt cut the opening thought’s preview about ninefold.
- Judge mid-training by what survives RL, with the untouched base as the bar. At 20M tokens on a strong base, no corpus cleared it, which makes dose and base strength the next variables to move.
- Put the teacher’s foresight where the student cannot copy it. ExpRL finds on math that imitating reference solutions collapses coverage, while using them only to score the model’s own attempts gives the best start for RL. RLMT, the second half of Tan et al.’s recipe, already uses the true continuation this way.
One caution from my own checks: on toy reasoning stories from Meta’s Self-Notes tasks, the bits-saved signal scored a note that merely names the upcoming entity above a correct intermediate step, so a prediction reward needs a control for naming. Whether privilege in the reward teaches reasoning where privilege in the target taught guessing is the next experiment.
One motivation for self-improving pretraining is adaptation where data is scarce, expensive, private, long-tail, or behaviorally underspecified. Synthetic continued pretraining is motivated by facts that appear rarely in small domain corpora, and improves learning by rearranging that knowledge into more learnable forms. Privacy-constrained continual pretraining is also emerging, with encrypted synthetic data pipelines for sensitive-domain adaptation.
My view is that smaller domain models often need reliable behavioral interfaces before post-training. Scientific agents, code agents, compliance analysts, medical-document assistants, internal enterprise copilots, and multilingual or domain-specific models all fit this shape. In those settings, the valuable synthetic target is structured behavior: a model that can plan, inspect, cite, verify, revise, call tools, recover from failed assumptions, and predict the next domain-relevant state. If those behaviors are bounded by what the base model can express, the place to shape them is earlier in the lifecycle than usual.
The recipe I would test next is to preserve a domain corpus, synthesize local reasoning traces from what is knowable at each point in the text, teach the interface, and reward it through downstream observable outcomes, with the teacher’s view of those outcomes in the reward. The blank and generic controls need to remain in that evaluation, because a thought can change behavior without improving it, and so does the untouched base, because each stage has to earn its place after RL.
Limitations and Closing
This is a small-scale adaptation of Tan et al., not a full reproduction. The lifecycle experiment uses Qwen3-0.6B-Base, a short RLMT run, and a smaller evaluation budget than the original paper, and the follow-up uses LFM2.5-1.2B-Base. The right comparison is whether the same training signals work at small scale, not whether the benchmark numbers match Tan et al.
- Each experiment uses one base model, one training-data teacher, and one mid-training run per corpus.
- The follow-up used 20M mid-training tokens against the paper’s roughly 10B, and GSM8K as the only RL task, for 200 steps. A larger budget could change the cost to RL in either direction.
- The continued-pretraining result comes from an LLM judge; every other result here uses exact likelihoods, answer checking, or string matching.
- The confabulation count matches exact strings, so it includes some true background knowledge and misses paraphrase. The causal prompt still invents about 1.35 specifics per opening thought.
- The untouched-base RL run and the after-RL measurements were added after the first results, and the after-RL measurements use one seed. The future-facts-removed corpus took three rewrite iterations and one redefined check to pass its manipulation check, all recorded before any of its outcomes.
- On the 0.6B models, the comparison between hindsight and causal teacher thoughts covers 128 passages and uses a frozen reader, so it shows what a thought is worth to the model reading it, not whether that model could learn to write it.
The main limits are scale and the absence of a later agentic-training comparison. These results support the claim that the lifecycle can be made trainable at small scale, and that the teacher’s view determines what a thinking corpus teaches. They are not a claim that this model learned a mature agentic reasoning policy.
Ordinary pretraining text supported several learning problems in this experiment, and self-improving pretraining and thinking SFT each left a measurable trace. The gap I cared about most, a model that responds to thought content before it can write useful thoughts, now has a mechanism: a thinking corpus teaches whatever its teacher could see. The next version of this pipeline should write thoughts from what is knowable and spend the teacher’s foresight on the reward. Whether that preparation makes later agentic post-training easier is still the next experiment, and this work gives it something concrete to test.
The pipeline code is in the synthetic-pretrain repository.